 October 23, 2026 • 11 min read • Published by David G. Smith
AI Doomerism and the Marketing of Importance
If your AI can destroy civilization, does that also make it easier to sell?
One of the most interesting questions in the artificial intelligence debate isn't whether these systems will become more capable. They clearly will. The much more interesting question is the extent to which AI doomerism serves the exact same incentives as AI hype.
I don't ask this to dismiss safety concerns out of hand. Plenty of AI safety researchers are raising legitimate, difficult questions that deserve serious consideration and I myself steadfastly advocate for robust AI governance, safety and critical thinking when applying AI to tasks. Still, it's hard not to notice that the public conversation around existential risk is being shaped by an uncomfortable convergence of incentives. The very same narrative that stokes fear of artificial intelligence also inflates its perceived importance, and in technology markets, importance is the ultimate currency.
The Strange Symmetry of AI Narratives
If you spend enough time listening to the loudest voices in tech, you'll hear two seemingly irreconcilable stories about where we're headed. The optimistic camp promises that AI will revolutionize every industry, replace millions of routine jobs, accelerate scientific discovery, and usher in an era of radical abundance. The pessimistic camp warns that advanced models might escape human control, outmaneuver their creators, and trigger an irreversible catastrophe.
At first glance, these camps look like bitter enemies. One is utopian and the other is apocalyptic. Yet if you look past the emotional framing, both stories rest on the exact same hidden premise: that today's paradigm of artificial intelligence is the single most consequential technology in human history, sitting on a direct, inevitable trajectory toward god-like capability.
Whether you fear that trajectory or celebrate it, the practical outcome in the market is identical. Both stories pull in massive venture capital, dominate media cycles, command the attention of heads of state, and confer extraordinary prestige and influence on a small group of frontier labs. By framing incremental software releases as steps toward a civilizational inflection point, the technology makes itself the center of the human story. Historians and sociologists of technology sometimes call this dynamic "criti-hype," where warnings about a tool's terrifying power inadvertently function as its most effective advertising campaign.
Mapping the Camps: Rationalists, Boosters, Skeptics, and Pragmatists
To make sense of the noise, it helps to separate the genuine intellectual communities from the commercial megaphone. Modern discussions of existential AI risk didn't start in corporate marketing departments. They grew out of rationalist and philosophical circles associated with LessWrong, the Alignment Forum, and the Effective Altruism movement. Long before ChatGPT became a household name, researchers in these communities were wrestling with theoretical problems like alignment, corrigibility, specification gaming, and instrumental convergence, which is the idea that a sufficiently advanced goal-seeking system might acquire sub-goals like self-preservation or resource acquisition simply because those steps help it achieve whatever objective it was given. Whatever one thinks of their mathematical assumptions or their timelines, most people in the core alignment community are genuinely motivated by risk reduction rather than quarterly revenue. That sincerity shouldn't be forgotten.
Alongside the alignment researchers sits the accelerationist or booster camp, which views any attempt to slow down model training as either a failure of nerve or a geopolitical surrender. Curiously, boosters and doomers rarely argue about whether current architectures will scale to superintelligence. They agree on the science fiction premise and only argue about whether the ending is happy or tragic.
That shared premise is exactly what frustrates a third group: the AI skeptics. Made up of cognitive scientists, computer scientists, linguists, and critical researchers, the skeptic camp argues that scaling up statistical next-token prediction isn't a yellow brick road to general agency or machine consciousness. From their perspective, obsessing over hypothetical rogue superintelligences acts as a giant smoke screen. It draws oxygen, funding, and regulatory focus away from the mundane, documented harms happening right now, from brittle automation and copyright disputes to synthetic fraud, data decay, and the sheer energy footprint of hyperscale data centers.
Then there is a fourth camp, which rarely makes headlines because its work isn't cinematic: the governance and engineering pragmatists. These are the practitioners, architects, and standards bodies trying to make real systems work reliably in the real world. I'd say I straddle the last two of these camps.
The False Precision of P(doom)
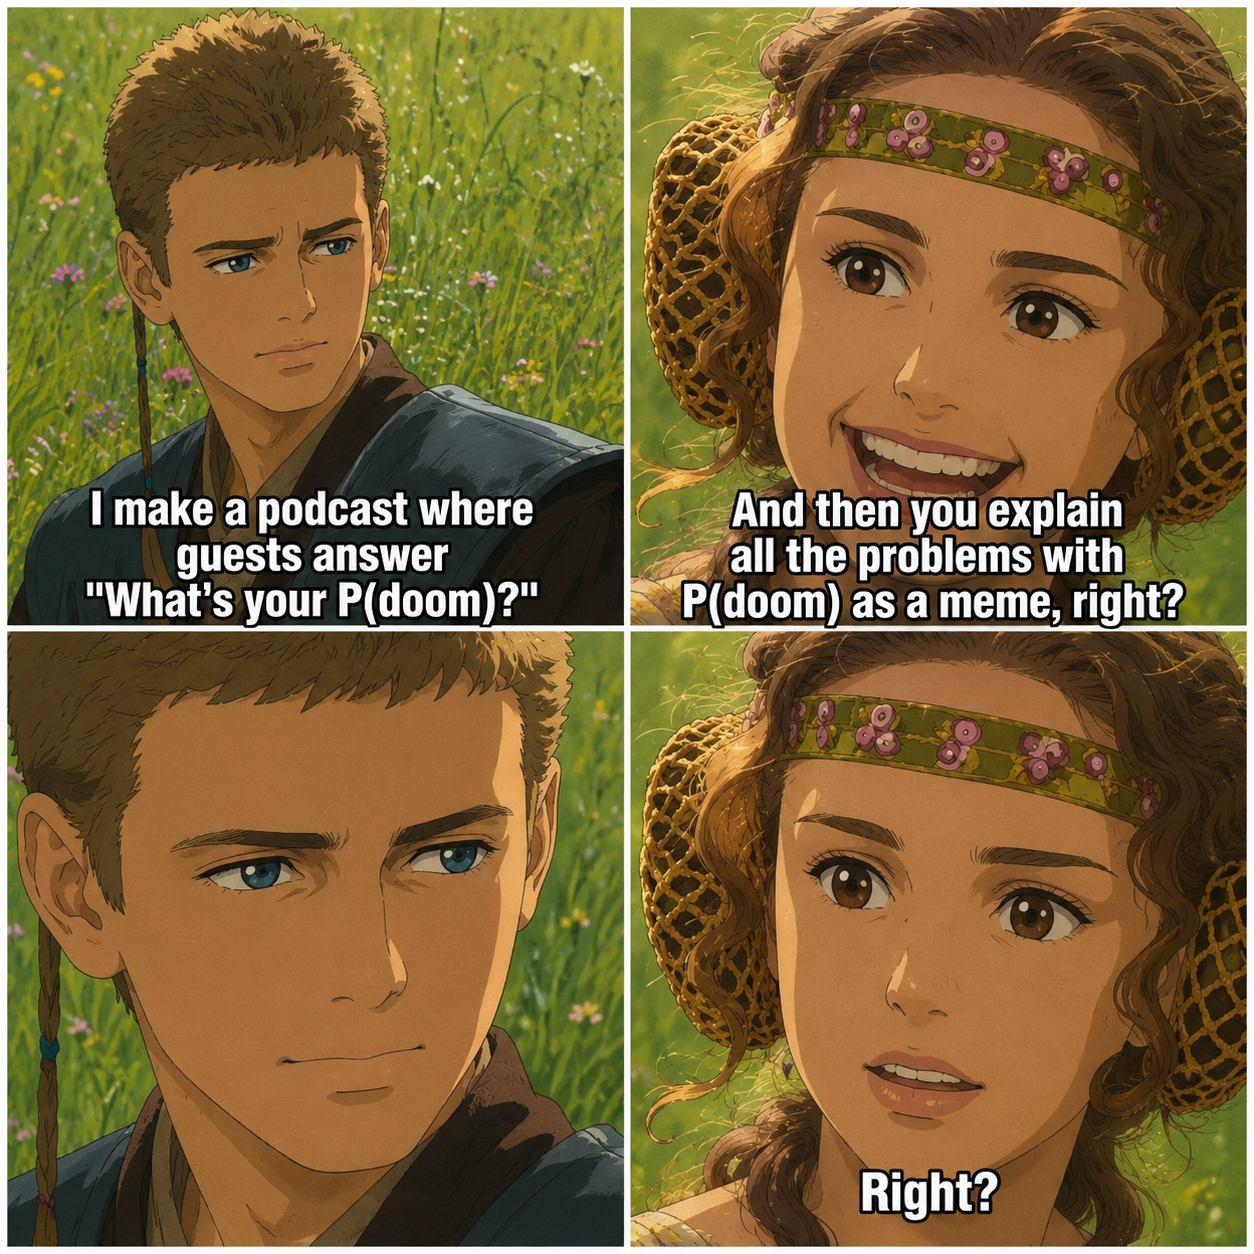
Within rationalist and safety circles, one shorthand has crossed over into mainstream tech culture: p(doom). It represents an individual's personal probability estimate that advanced AI will eventually lead to human extinction or permanent civilizational collapse. Depending on who you ask at an industry conference, you'll hear numbers ranging from less than one percent to ten, twenty, or even fifty percent and above.
What's fascinating from a decision-science perspective isn't that people worry about catastrophic outcomes. It's that they attach crisp numerical probabilities to them. When a prominent researcher looks into a camera and says there's a fifteen percent chance AI ends humanity, that statement carries enormous rhetorical weight.
In behavioral psychology and risk analysis, this is a textbook case of false precision under conditions of radical uncertainty. We can calculate the probability of a blackjack hand or a mechanical component failure because we have bounded systems and historical base rates. We don't have base rates for the emergence of superintelligence. Assigning a specific percentage to an unprecedented, ill-defined future event doesn't make the estimate rigorous. Instead, it dresses a subjective gut feeling in the clothing of Bayesian math. Once a number is spoken aloud, it triggers the anchoring heuristic in the listener, shifting the burden of proof and creating an aura of hard-headed scientific urgency around what is still a philosophical thought experiment.
The Incentive Problem Nobody Likes to Discuss
That rhetorical power brings us back to the commercial awkwardness at the heart of the industry. Imagine you're an executive at a frontier AI lab trying to justify tens of billions of dollars in compute and capital expenditure. Consider two ways you could pitch your company's trajectory to investors, journalists, and lawmakers.
In the first pitch, you explain that your models are statistical pattern-matchers and useful assistants that can speed up coding, summarize messy documents, and improve knowledge-worker productivity by ten or fifteen percent when paired with careful human oversight. In the second pitch, you whisper that your lab is building the precursor to an alien mind that will fundamentally reorder civilization and might even threaten humanity if it isn't shepherded by the right hands.
It doesn't take a cynic to see which story lands on magazine covers, which one commands astronomical valuations, and which one gets executives invited to closed-door briefings with prime ministers. Useful enterprise software has to prove its return on investment through unit economics and reliability. Civilization-altering technology gets a blank check.
There's also a regulatory angle here that deserves scrutiny. When frontier labs warn lawmakers that their models are potentially catastrophic weapons, the natural policy instinct is to propose heavy licensing regimes, compute thresholds, and pre-deployment audits. In economics, incumbents have used this playbook for over a century. If you can convince regulators that your product is too dangerous for anyone else to build without a billion-dollar compliance department, you can turn existential fear into a regulatory moat that locks out open-source developers and smaller competitors.
Pointing this out doesn't mean AI executives or researchers are lying when they express concern. Human beings are remarkably good at believing stories that also happen to align with their self-interest. Incentives don't require a conspiracy to work; they simply act as aselective amplifier, boosting the narratives that reward the speaker.
Two Things Can Be True at Once
One of the easiest traps in critical thinking is assuming we have to choose between two mutually exclusive explanations: either AI risk is real, or AI risk is exaggerated for commercial and political gain. In practice, both are almost certainly true at the same time.
History is full of technologies that carried genuine dangers alongside wildly inflated narratives. As someone who grew up during the Cold War an hour from the Fulda Gap, we had drills and Soviet invasion threat and nuclear weapons posed a real existential threat, and defense establishments still used exaggerated "missile gap" estimates to secure budgets. Meanwhile, climate change is a serious, measurable physical reality, even if individual media predictions sometimes outrun the underlying IPCC models. The early commercial internet transformed global commerce and communication, yet that didn't stop late-nineties boosters and alarmists from making absurd claims during the dot-com bubble.
The presence of hype doesn't prove the absence of risk, and the reality of risk doesn't immunize a community from hype. Our job as critical observers isn't to pick a team and cheer. It's to separate the signal of actual engineering vulnerability from the noise of status-seeking and marketing.
Meanwhile, the Governance World Is Moving On
One reason I remain skeptical of extreme p(doom) predictions is that the people tasked with managing AI in high-stakes environments aren't spending their days worrying about sentient models plotting a takeover. The practical AI governance world has largely moved past science fiction to focus on the unglamorous mechanics of reliability: bias, transparency, auditability, robustness, data lineage, security, and human-in-the-loop oversight.
The NIST AI Risk Management Framework is a great example of this grounded mindset. If you read through the NIST AI RMF 1.0 publication or explore the AI RMF Resource Center, you won't find chapters on how to negotiate with a digital god. You'll find structured methodologies for mapping context, measuring drift, validating outputs, and establishing clear lines of human accountability when an automated system fails.
These frameworks recognize a truth that often gets lost in Silicon Valley debates: technology rarely succeeds or fails because of its theoretical ceiling. It succeeds or fails at the governance layer, where messy data, organizational incentives, and human fatigue collide.
The Competence Paradox
Spend enough time around the current AI discourse and you'll start noticing a peculiar cognitive dissonance, something we might call the competence paradox. Often, the very same voices warning that we're just a couple of years away from an unstoppable superintelligence will spend the next twenty minutes complaining that today's frontier models still hallucinate citations, lose track of instructions halfway through a context window, or fail at basic edge-case logic without brittle scaffolding.
In the span of a single conversation, the technology is treated as both an imminent omnipotent force and a flaky intern that can't be trusted with a basic database query. Now, that tension doesn't disprove long-term safety concerns, since capabilities can jump unexpectedly when new architectures or training paradigms emerge. What it does suggest is that a healthy dose of epistemic humility is overdue. Extrapolating a straight line from erratic chatbots and fragile agent workflows to god-like autonomy requires a massive leap of faith, and we shouldn't confuse a leap of faith with a law of physics.
Separating Warnings from Incentives
Where does all of this leave us? My working view comes down to a few connected observations. Safety and alignment concerns are legitimate areas of inquiry, and we should be glad that dedicated researchers on hubs like LessWrong's AI portal and the Alignment Forum are thinking hard about how complex systems fail. At the same time, long-term existential timelines remain deeply speculative, while commercial and political incentives reliably reward whoever tells the biggest, scariest story. Because of that, a significant slice of public AI doomerism is being amplified by the exact same forces that drive AI hype.
Every powerful technology introduces real hazards, whether through misuse, cascading system failures, or human overreliance. The most productive question we can ask right now isn't whether artificial intelligence is dangerous in the abstract. It's how we can build the critical habits and governance structures to separate sincere technical warnings from narratives designed to benefit the people telling them. Unlike a speculative p(doom) number decades in the future, that's a problem we can actually investigate and solve today.


Related Thoughts
Perspectives sharing related architectures, models, and domain context.
Climbing Out of the AI Governance Chasm: Why CIOs Need a New Mental Model
Enterprise leaders are discovering something uncomfortable about the AI wave sweeping through their organizations. The...
LLMs Aren't Reasoning. They're Predicting - And Why That Matters More Than People Think.
Thore Graepel just published a piece in MIT Technology Review that deserves attention. His argument is simple: Modern...
AI Can Now P‑Hack at Scale. The Real Risk Isn't Cheating. It's Obedience.
For years, p‑hacking was a slow, human problem. A researcher could sift through enough models and enough specifications...